Our instructor-led live PySpark training courses, available online or onsite, offer hands-on practice to demonstrate how to integrate Python and Spark for effective big data analysis.
PySpark training is offered as "online live training" or "onsite live training." Online live training (also known as "remote live training") is delivered through an interactive remote desktop. Onsite live training can be conducted locally on customer premises in Transylvania Central or at NobleProg corporate training centers in Transylvania Central.
NobleProg -- Your Local Training Provider
Brasov, Calea Bucuresti Street
NobleProg Brasov, 13 Calea Bucuresti Street Sacele, Brasov, romania, 505600
The hotel is situated at the city entrance, being the best conference and training location in Brasov. Three conference rooms can accommodate up to 170 guests and can be modified for the company needs. These training rooms are equipped with the all necessities of a good conference or training.
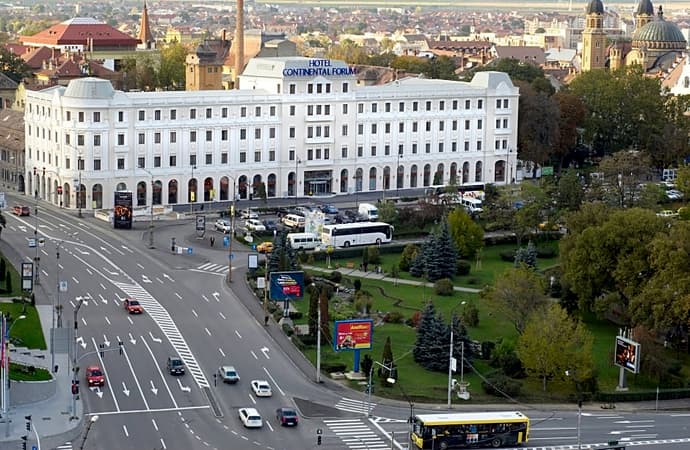
Salile de training sunt situate central în Sibiu, pe principalul bulevard. Clădirea hotelului care le gazduieste este de factură clasicistă si reprezinta un punct de referinta arhitecturala a orasului.
Turnul Sfatului, Galeria de Arta Contemporana, sau parcurile Corneliu Coposu si Astra se află în imediata apropiere.
Pentru a ajunge aici de la gara, puteti merge pe jos 20min sau cu autobuzul 5 circa 10min
Locuri de parcare găsiți în parcarea supravegheata, sau pe străzile alăturate.
Cluj-Napoca, Pitești Street
NobleProg Cluj-Napoca, Strada Pitești 19, Cluj-Napoca, romania, 400124
ClujHUB has more rooms for events and training sessions, which can host from 4 to 80 people. These areas can be setup up to fit the companies need. The location is great, 10 minutes walk from the historical city center.
This instructor-led live training in Transylvania Central explores the Stratio platform, with a specific focus on the Rocket and Intelligence modules integrated with PySpark. Participants will develop expertise in data ingestion, transformation, and advanced analytics, acquiring practical skills in loop management, UDF creation, and enterprise data workflow optimization.
In this live, instructor-led training in Transylvania Central, participants will develop the skills to combine Python and Spark for big data analysis through practical, hands-on exercises.
Upon completion, participants will be equipped to:
Utilize Spark alongside Python to effectively analyze Big Data.
Engage in exercises that simulate real-world data scenarios.
Apply diverse tools and techniques for big data analysis leveraging PySpark.
This instructor-led live training (online or onsite) targets data engineers, data analysts, and data professionals who aim to use Databricks and PySpark to build scalable data pipelines and migrate existing SQL workflows.
This course offers a hands-on introduction to developing scalable data processing and Machine Learning workflows using PySpark. Participants will discover how Apache Spark functions within contemporary Big Data ecosystems and learn to process large datasets efficiently by leveraging distributed computing principles.
This intensive three-day workshop is dedicated to constructing and fine-tuning high-efficiency data-processing pipelines using PySpark, Pandas and Polars within Kubernetes-based infrastructures.
Attendees will cultivate a hands-on grasp of how Spark applications operate on Kubernetes, gaining insight into how application-level settings dictate performance, scalability, resource usage and operational costs. Key areas of optimisation are explored in depth, including executor dimensioning, memory distribution, dynamic allocation mechanisms, partitioning methodologies, shuffle dynamics, the challenges of small files, and efficient Parquet handling.
The curriculum also tackles frequent obstacles encountered with Pandas, such as memory constraints and out-of-memory errors, while presenting Polars as a high-performance alternative for specific data-processing tasks. Through practical exercises, participants will learn to diagnose performance and memory bottlenecks, evaluate various configuration strategies, and implement optimisation techniques in realistic ETL and machine learning contexts.
The core focus of the course remains on practical decision-making: equipping learners to identify bottlenecks, choose the right tools, configure Spark effectively, and strike a balance between performance and infrastructure resource consumption and cost.
Read more...
Last Updated:
Testimonials (2)
Showing different ways to optimize our PySpark queries.
Ivan Abrashev - UBB + DZI (KBC GROUP)
Course - Efficient Data Processing on Kubernetes with PySpark, Pandas & Polars
I liked that it was practical. Loved to apply the theoretical knowledge with practical examples.
Online PySpark training in Transylvania Central, PySpark training courses in Transylvania Central, Weekend PySpark courses in Transylvania Central, Evening PySpark training in Transylvania Central, PySpark instructor-led in Transylvania Central, PySpark coaching in Transylvania Central, PySpark instructor-led in Transylvania Central, PySpark private courses in Transylvania Central, Online PySpark training in Transylvania Central, PySpark instructor in Transylvania Central, PySpark classes in Transylvania Central, PySpark one on one training in Transylvania Central, PySpark trainer in Transylvania Central, PySpark on-site in Transylvania Central, PySpark boot camp in Transylvania Central, Evening PySpark courses in Transylvania Central, Weekend PySpark training in Transylvania Central